SimplyWins
A decision tool that tests rules, classic machine learning and large language models against each other, then recommends the simplest approach that meets the bar.
01Problem
Teams pick a model before defining the job.
Many tasks, such as emailing a parent when a result is recorded, need no AI at all. Complexity has to earn its place.
02What I built
A questionnaire, then a benchmark.
SOLO PRODUCT
AA questionnaire that works without an API key and returns an assessment from a fixed rubric.
BA benchmark library that runs keyword rules, TF-IDF/logistic regression and GPT OSS 20B/120B on four public text-classification datasets, with matched samples, leakage checks, per-class error analysis, Wilson intervals and McNemar tests.
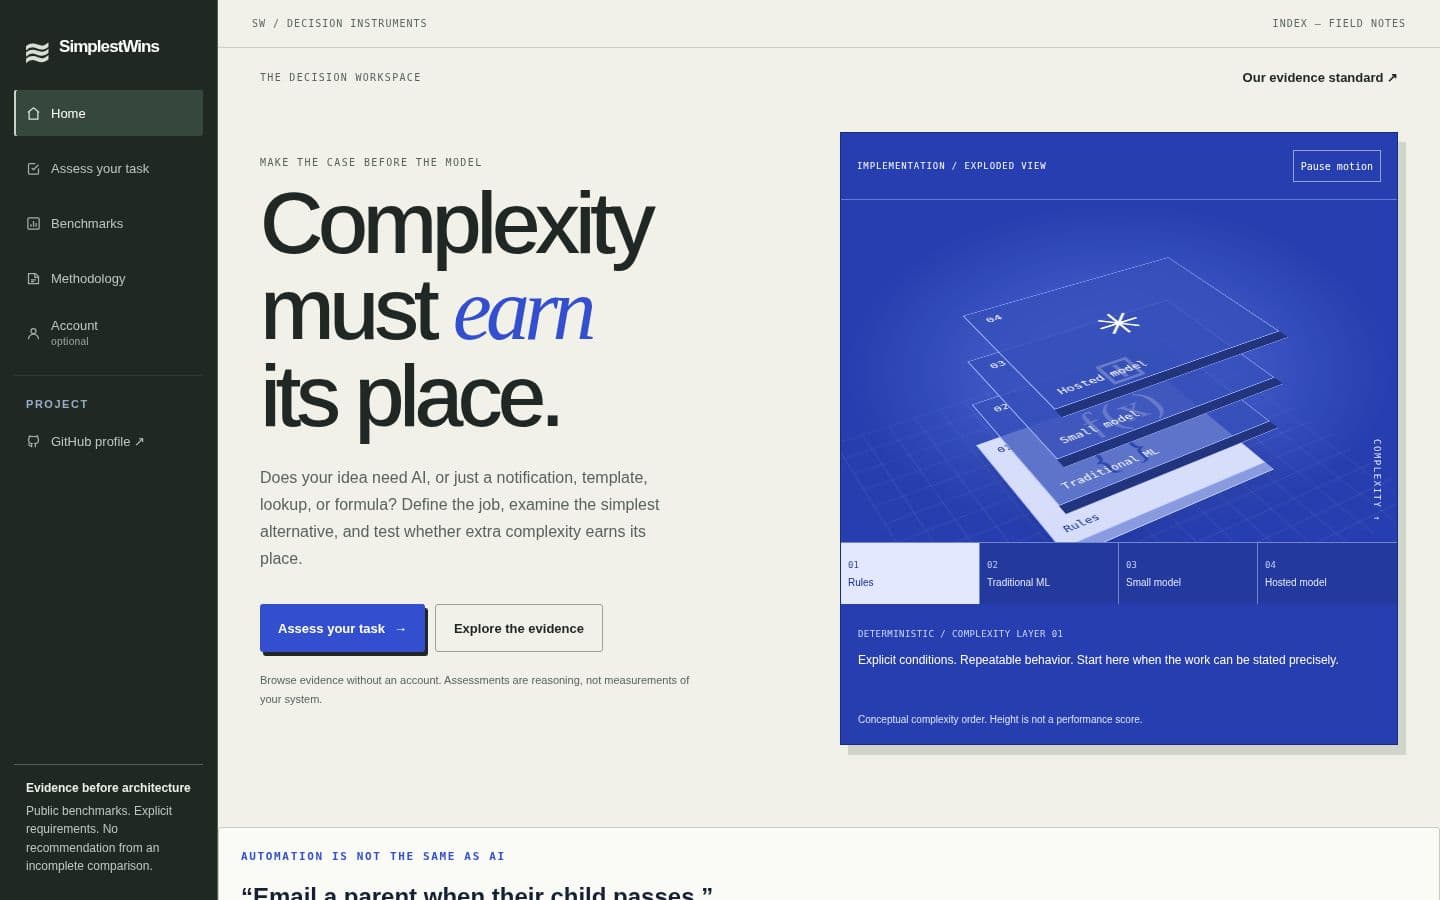
CAPI keys for Anthropic, OpenAI, Groq and Kimi encrypted server-side (Firebase Auth + Fernet) and never sent back to the browser, verified by a CI browser gate. An interactive exploded 3D method stack on the home page.
03Result
Four public corpora. Four methods measured on every published task. 584 automated tests in the private README (284 unit, 196 integration, 104 benchmark). A production browser test on 11 Sep 2026 passed end to end with a stored Groq key.
04Stack
PythonFastAPIscikit-learnGroq
05Gallery